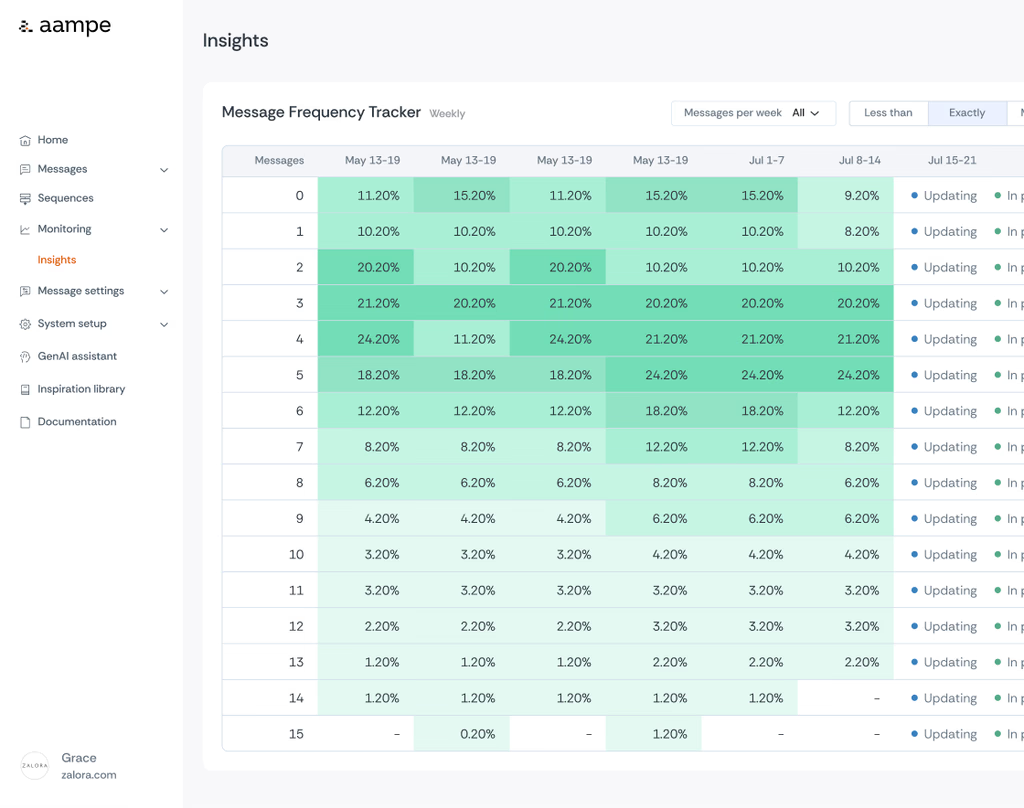
Drawing from a random distribution in SQL
Aampe is a reinforcement learning agent that personalizes emails, web/push notifications, SMS and WhatsApp messages for users. Some of the data workloads within the agent are written in SQL that is executed on GCP’s BigQuery engine. We use this stack because it provides scalable computational capabilities, ML packages and a straightforward SQL interface. To improve […]
Which discount strategy is the most effective?
Since last November, I’ve logged 3,492 push notifications from over 100 of the most popular eCommerce apps If you have an extra phone lying around, logging push notifications is a relatively easy way to get insights into a retailer’s messaging and discount strategy. Nevertheless, not everyone has an extra phone (or several months of time […]
What is Data Warehousing? Concepts, Tools, Examples
Data warehousing is an important component of enterprise data management and business intelligence. It entails the process of collecting, consolidating, and organizing vast amounts of data from various sources into a single, comprehensive repository. This centralized system is designed to support and enhance the data analysis, reporting, and query capabilities that businesses need to make […]
The hidden costs of canvas journey builders
We have often heard that campaign and journey visual builders (e.g., Braze’s Canvas feature) are attractive features in conventional CRM and CEM platforms. But having paid close attention for a long time, we’ve observed that the most enthusiastic marketers are the ones that haven’t used the Canvas-type builders extensively. More importantly, we noticed that lifecycle […]
ELT Explained: Optimize Data Processing Efficiency
In the rapidly evolving landscape of data science, the methodologies of Extract, Load, Transform (ELT) and Extract, Transform, Load (ETL) have been instrumental in managing vast data reservoirs efficiently. ELT marks a paradigm shift by loading data into a target data warehouse before applying transformation processes. This approach, contrasting with the traditional ETL methodology where […]
What is an Enterprise Data Warehouse (EDW)?
An enterprise data warehouse (EDW) represents a critical component of modern business intelligence, serving as a centralized repository for all of your company’s critical data. By compiling structured data from various operational systems, the EDW empowers your analytics applications to provide comprehensive insights across the entire organization. Through this consolidation, an EDW simplifies the process […]
What is ETL (Extract, Transform, Load)?
ETL, an acronym for Extract, Transform, Load, is a cornerstone process in the field of data science, crucial for translating raw data into valuable insights. ETL processes begin by extracting data from multiple sources, which can include databases, CRM systems, or flat files. Once the data is extracted, it undergoes a transformation phase where it […]
Data Warehouse Architecture: Foundations and Best Practices
Understanding the structure of data warehouse architecture is crucial for effectively managing and analyzing the large volumes of data that businesses accumulate. A data warehouse acts as a centralized repository where information is stored from various sources in a structured format, enabling complex queries and analysis. This centralization supports the strategic decision-making process by providing […]
Data Warehouse vs Data Lake: Key Differences Explained
A data warehouse and a data lake are two fundamentally different storage solutions that cater to diverse business needs. Data warehouses provide you with a highly structured environment designed for storing, processing, and analyzing data, specifically formatted for query and analysis. This makes data extraction swift and reliable, with the benefit of obtaining actionable insight […]
Data Ingestion Pipeline: Building Blocks for Efficient Data Management
The data ingestion process is crucial in data warehousing, helping you to manage and leverage your data more effectively. At its core, it involves the transportation of data from various sources into a storage medium where it can be accessed, used, and analyzed by an organization. A data pipeline typically encompasses several stages, including data […]